IHA Cloud

Author name: Shivam Pokhriyal

DevOps Automation

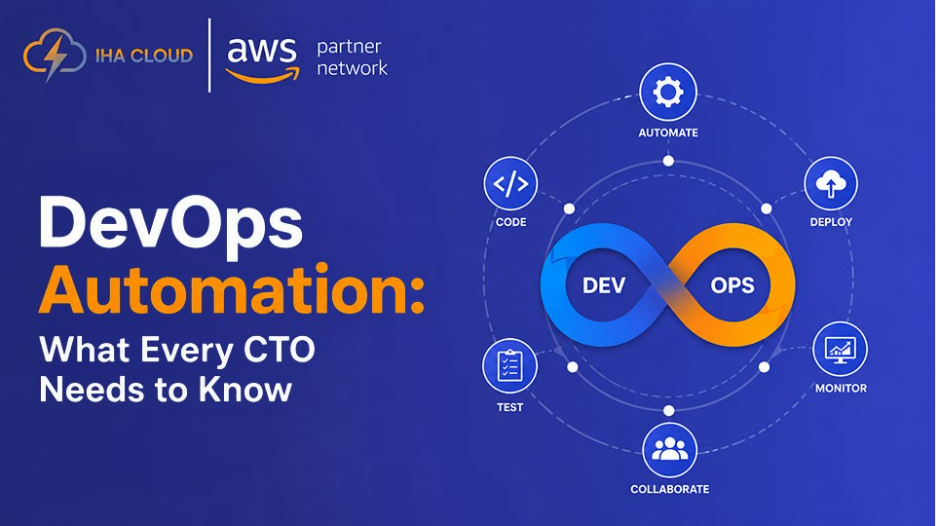
DevOps Automation: What Every CTO Needs to Know

If a production release still depends on a checklist, someone manually provisioning infrastructure, or an engineer watching the deployment, your DevOps process still relies heavily on people.  That isn’t necessarily a bad thing. Not everything should be automated. But repetitive work that happens every day is usually a poor use of engineering time.  For a CTO, DevOps automation is really about one question:  Where can automation give the engineering team more leverage without giving up control?  What Does DevOps Automation Actually Mean?  DevOps automation means using tools and workflows to handle repeatable work across software delivery, infrastructure, security, and operations.  That can include CI/CD, Infrastructure as Code, automated testing, cloud provisioning, security checks, monitoring, and automated responses to known issues.  A simple rule is worth remembering:  Don’t automate a messy process. Standardize it first.  Otherwise, you may just automate the inconsistency.  Start With the Problem, Not the Tool  It’s easy to get distracted by tools. Terraform, Kubernetes, GitHub Actions, CloudFormation—the list goes on.  But the first question shouldn’t be “Which tool should we use?”  Ask:  If your team manually handles 30 deployments a week, that’s a much stronger automation candidate than an architecture decision that happens twice a year.  Automate where the leverage is highest.  Where CTOs Should Look First  Make Releases Repeatable  CI/CD can automatically build code, run tests, perform security checks, and deploy approved changes.  The benefit isn’t simply faster deployment. It’s removing unnecessary handoffs and making the release process less dependent on individual engineers.  DORA research has linked continuous delivery capabilities with stronger software delivery performance and operational outcomes.  The question to ask is:  Can we release faster without making production less reliable?  Stop Building Infrastructure by Hand  Infrastructure as Code lets teams define cloud infrastructure in version-controlled configurations instead of creating environments manually.  With tools such as Terraform or AWS CloudFormation, a staging environment can be reproduced from an approved configuration instead of rebuilt from scratch.  That matters when teams grow. Infrastructure knowledge shouldn’t live inside one engineer’s head.  DORA research has identified Infrastructure as Code as an important capability associated with stronger software delivery performance.   Let Testing Keep Up With Development  Faster coding doesn’t help much if testing remains manual.  Automated unit, integration, API, regression, and security testing can catch problems before they reach production.  This matters even more as AI-assisted development becomes common. DORA’s 2025 research reports widespread workplace AI adoption and productivity gains, while warning that AI can amplify weaknesses already present in software delivery systems.   In simple terms:  If developers can produce code faster, your delivery controls need to keep up.  Automate Cloud Operations Carefully  Cloud automation can handle provisioning, scaling, backups, tagging, and recovery workflows.  For example, an AWS application can scale resources when traffic increases and reduce capacity when demand falls.  But automation isn’t automatically cost optimization. Poor scaling rules, unnecessary environments, or excessive logging can create new cloud spend.  Automate for efficiency, then measure the result.  Build Security Into the Workflow  Security shouldn’t be a final check before deployment.  Automated workflows can scan code, dependencies, containers, infrastructure configurations, secrets, and cloud permissions throughout the delivery process.  A vulnerable dependency can trigger a deployment block before it becomes a production problem.  That’s a much stronger model than asking a security team to review everything at the end.  Automate Known Problems  Monitoring becomes more useful when it can trigger a predefined response.  For a known failure, the workflow might be:  Detect → Respond → Notify → Record  An unhealthy application instance could be replaced automatically while the team is alerted.  But don’t automate decisions that require context.  Known, predictable problems are good automation candidates. Ambiguous incidents still need people.  A Simple Before-and-After  Consider a typical release.  Before:  Developer merges code → manual testing → infrastructure check → deployment → dashboard monitoring → manual rollback.  After:  Code merge → automated tests → security checks → IaC validation → deployment → health checks → predefined rollback.  The difference is more than fewer clicks.  The second process means fewer handoffs, more consistent releases, faster feedback, and less repetitive work for engineers.  That’s the kind of improvement a CTO should care about.  Where Does Your Automation Stand?  Not every company needs fully autonomous operations. A simple maturity model helps identify the next step:  1. Manual — People perform the work.  2. Scripted — Scripts reduce repetitive effort.  3. Standardized — Teams follow the same process.  4. Automated — Systems execute it.  5. Self-Service — Teams safely trigger approved workflows.  6. Policy-Driven — Automation enforces rules automatically.  The goal isn’t to reach Level 6 everywhere. A production change may still need human approval while a development environment can be fully self-service.  Don’t Create Automation Debt  Automation can create problems of its own.  Brittle pipelines, duplicate scripts, undocumented workflows, and tools that only one engineer understands can make the environment harder to manage.  So ask:  Can the team understand, maintain, and troubleshoot what we’ve automated?  If the answer is no, you’ve probably traded manual work for automation debt.  Measure What Actually Changed  Don’t measure success by how many workflows you’ve automated.  Look at:  DORA metrics help measure software delivery performance, but they don’t prove that automation itself caused an improvement. Pair delivery metrics with business and operational measures to understand the actual return.   The CTO View  Good DevOps automation isn’t about having the most tools or the most automated pipelines.  It’s about giving engineers more time to solve important problems while making delivery safer and more predictable.  Start with work that is frequent, repetitive, predictable, and costly to perform manually.  Standardize it. Automate it. Measure it. Then simplify it.  That’s how automation becomes an engineering advantage rather than another layer of complexity. 

DevOps Automation: What Every CTO Needs to Know Read More »
AWS CloudTrail and Config: Building an Audit-Ready Cloud Environment 

When something changes unexpectedly in an AWS account, the first question is always the same: who did this, and when? Without CloudTrail and Config enabled, that question often has no answer. With them, it takes minutes to find.  AWS CloudTrail — The Record of Every Action  CloudTrail logs every API call made in your AWS account, whether it came from the console, CLI, SDK, or another AWS service.  AWS Config — The State of Your Resources Over Time  Where CloudTrail tells you what action was taken, Config tells you what your resources actually looked like before and after — and whether they match your defined rules.  Setting Both Up Properly  What This Solves in Practice  Common Gaps  CloudTrail and Config are two of the least visible AWS services in daily operations, and two of the most important the moment something goes wrong or an audit comes due. Both are inexpensive to run and expensive to have missed enabling.

AWS CloudTrail and Config: Building an Audit-Ready Cloud Environment  Read More »

Building a DevSecOps Pipeline: Integrating Security into Your CI/CD

Building a DevSecOps Pipeline: Integrating Security into Your CI/CD 

Security reviews that happen after code is already deployed catch problems too late, and usually too slowly to matter. DevSecOps means moving those checks earlier — into the pipeline itself — so vulnerabilities are caught before they ever reach production.  What Changes With DevSecOps  Traditional workflows treat security as a separate, later step. DevSecOps treats it as part of the same pipeline that builds and tests the code, running automatically on every change.  Where Security Checks Fit in the Pipeline  A Practical Pipeline Order  Keeping It From Slowing the Team Down  Common Mistakes  The Real Goal  DevSecOps is not about adding more steps for their own sake — it is about making sure security scales at the same pace as deployment frequency. A team deploying multiple times a day needs security checks that run automatically every time, not a manual review that can only happen occasionally.

Building a DevSecOps Pipeline: Integrating Security into Your CI/CD  Read More »

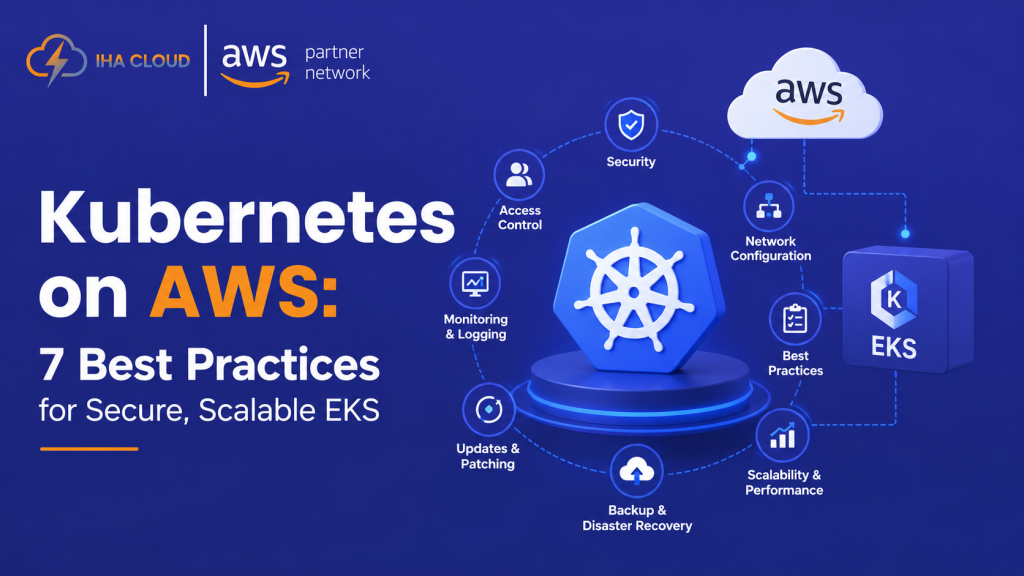
Kubernetes on AWS: 7 Best Practices for Secure, Scalable EKS

Kubernetes on AWS: 7 Best Practices for Secure, Scalable EKS 

Running Kubernetes on AWS isn’t difficult. Running it efficiently in production is.  You can create an Amazon EKS cluster quickly. The harder questions come afterward: How should your VPC be designed? Should you use EC2, Fargate, or EKS Auto Mode? How should workloads scale? How do you secure AWS access? And how do you prevent Kubernetes from quietly increasing your AWS bill?  Kubernetes is now firmly established in production. CNCF reported that 82% of container users were running Kubernetes in production, while Kubernetes is also becoming increasingly important for AI inference workloads.  For organizations adopting Kubernetes on AWS, Amazon EKS combines managed Kubernetes with AWS compute, networking, security, storage, and other cloud services.  But creating a cluster is only the beginning.  What Is Kubernetes on AWS?  Kubernetes on AWS means running Kubernetes workloads on AWS infrastructure, most commonly through Amazon Elastic Kubernetes Service (Amazon EKS).  A simplified Amazon EKS architecture looks like:  Users → Load Balancer → EKS → Pods → AWS Services  EKS is a strong fit for:  But Kubernetes isn’t automatically the right answer. For a simple application, a managed service with less operational overhead may be a better choice.  The goal isn’t to use Kubernetes because it’s popular. It’s to use it when its flexibility and scalability justify the complexity.  7 Kubernetes on AWS Best Practices 1. Design Your AWS Network Before Deploying EKS  Your EKS architecture starts with your AWS VPC, not Kubernetes.  A common production pattern is:  Internet → Application Load Balancer → Private Subnets → EKS → AWS Services  Plan for:  The AWS Load Balancer Controller can connect Kubernetes services and ingress resources with AWS load-balancing infrastructure.  Networking also affects your AWS bill. NAT Gateway usage and cross-AZ data transfer can become meaningful costs as traffic grows.  Best practice: design traffic flow, security boundaries, and expected network costs before deploying production workloads.  2. Design for Multi-AZ Resilience  Running EKS across multiple Availability Zones doesn’t automatically make an application highly available.  Your workloads need to be distributed correctly too.  Use:  For example, six replicas running in one Availability Zone can still fail together during an AZ outage.  So don’t just ask:  “Is my EKS cluster highly available?”  Ask:  “Can my application continue serving customers when infrastructure fails?”  That is the difference between deploying Kubernetes and designing it for production.  3. Choose the Right EKS Compute Model  EKS gives you several ways to run workloads.  Amazon EC2  Best when you need greater infrastructure control, specialized compute, GPUs, or deeper cost optimization.  AWS Fargate  Useful when reducing server management is more important than node-level control and your workloads fit Fargate’s supported model.  EKS Auto Mode  Useful when you want Kubernetes while reducing the amount of infrastructure management your team performs. It automates aspects of compute provisioning and cluster infrastructure.  Don’t choose based on price alone.  Start with:  Workload requirements → Required control → Operational overhead → Cost  That usually leads to a better decision than simply choosing the cheapest compute option.  4. Secure AWS Access With Workload Identity  AWS secures the underlying infrastructure, but your team remains responsible for workload and Kubernetes security.  Use AWS IAM and Kubernetes RBAC together and apply least privilege.  For workloads that need AWS permissions, use EKS Pod Identity or IAM Roles for Service Accounts (IRSA) instead of distributing long-lived credentials.  A strong baseline includes:  For example, a payment service that only needs access to one secret shouldn’t receive broad permissions across the AWS account.  Give every workload only the permissions it actually needs.  5. Use Autoscaling at Multiple Levels  Kubernetes scaling isn’t simply about adding pods.  Think about three layers:  Pod scaling  Use the Horizontal Pod Autoscaler (HPA) to adjust application replicas based on appropriate metrics.  Compute scaling  Use node autoscaling solutions such as Karpenter to provision suitable compute capacity as workloads change.  Application scaling  Look beyond Kubernetes. Databases, queues, caches, and external APIs can become the real bottlenecks.  For example:  Traffic doubles → HPA adds pods → database reaches capacity → application still slows down.  Adding more pods won’t fix that problem.  Scale the bottleneck, not just the container count.  6. Build Observability Before Production  Kubernetes creates operational data across infrastructure, clusters, and applications. Without proper observability, diagnosing an outage becomes a guessing game.  Use three layers:  Metrics → Logs → Traces  Monitor:  Layer  Examples  Infrastructure  CPU, memory, network  Kubernetes  Pod restarts, scheduling failures  Application  Latency, errors, throughput  Business  Transactions, conversions  AWS services such as CloudWatch can be combined with technologies such as Prometheus, Grafana, and OpenTelemetry.  Each solves a different part of the observability problem: infrastructure monitoring, metrics, visualization, and telemetry/instrumentation.  The objective isn’t to collect more data.  It’s to answer:  What failed? When? Which workload? Who is affected?  7. Automate Deployments and Control Costs  A repeatable AWS Kubernetes deployment workflow can look like:  Git → CI/CD → Container Registry → GitOps → EKS  Use Infrastructure as Code for AWS infrastructure and GitOps for Kubernetes configuration. Tools such as Terraform, CloudFormation, and Argo CD can reduce manual changes and configuration drift.  Keeping deployment configuration in Git also creates a versioned, reviewable source of truth for production.  CNCF has reported strong adoption of GitOps practices and Argo CD within the Kubernetes ecosystem.  For cost optimization, use:  Measure → Right-size → Automate → Review  Evaluate:  For example, if an application requests 4 vCPUs but consistently uses less than 1, its resource configuration deserves review.  Kubernetes cost optimization isn’t about choosing the cheapest infrastructure. It’s about paying for capacity your workloads actually need.  A Practical Kubernetes on AWS Architecture  Consider a SaaS platform using:  Users → ALB → EKS → RDS  with:  Multi-AZ + HPA + Karpenter + Pod Identity + Secrets Manager + CloudWatch  The ALB handles incoming traffic, EKS orchestrates containers, HPA responds to application demand, Karpenter provides compute capacity, Pod Identity controls AWS access, Secrets Manager protects credentials, and CloudWatch provides operational visibility.  In a real environment, additional services such as Route 53, ElastiCache, S3, queues, or CDNs may also be part of the architecture.  The important principle

Kubernetes on AWS: 7 Best Practices for Secure, Scalable EKS  Read More »

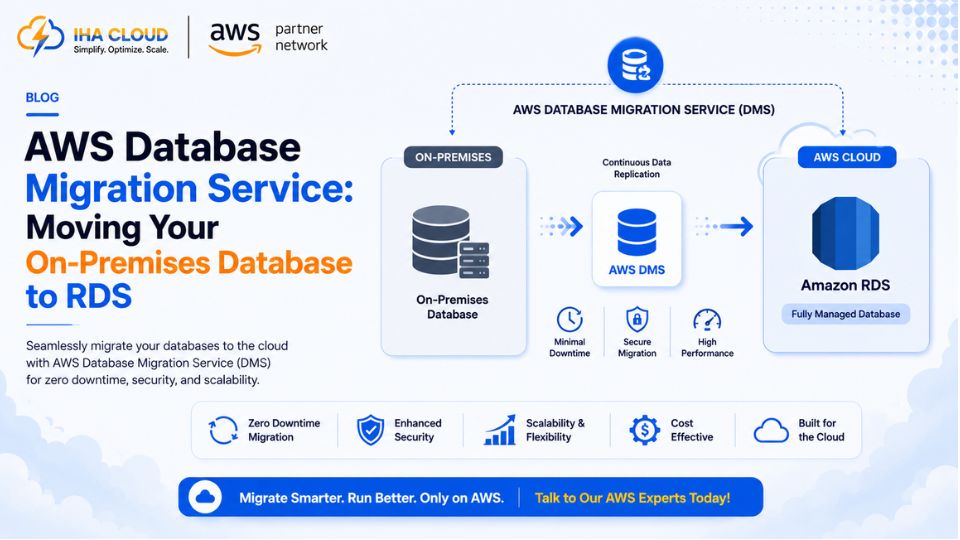
AWS Database Migration Service: Moving Your On-Premises Database to RDS

AWS Database Migration Service: Moving Your On-Premises Database to RDS

Migrating a database is not like migrating a web server — the data has to arrive intact, in the right order, with minimal or no downtime for whatever depends on it. AWS Database Migration Service (DMS) exists specifically to handle this without requiring the database to go offline for hours.  What DMS Actually Does  DMS replicates data from a source database to a target database, and can keep them in sync continuously until you are ready to cut over.  The Migration Process  Minimizing Downtime  Common Pitfalls  Why This Beats a Manual Migration  A manual database migration usually means a maintenance window, a backup, a restore, and hoping nothing changed in between. DMS keeps the source live and continuously replicates changes, which turns a high-risk, all-at-once event into a controlled, verifiable process — and that difference is exactly what makes it worth using for any production database migration. 

AWS Database Migration Service: Moving Your On-Premises Database to RDS Read More »

AWS Elastic Load Balancing Explained:

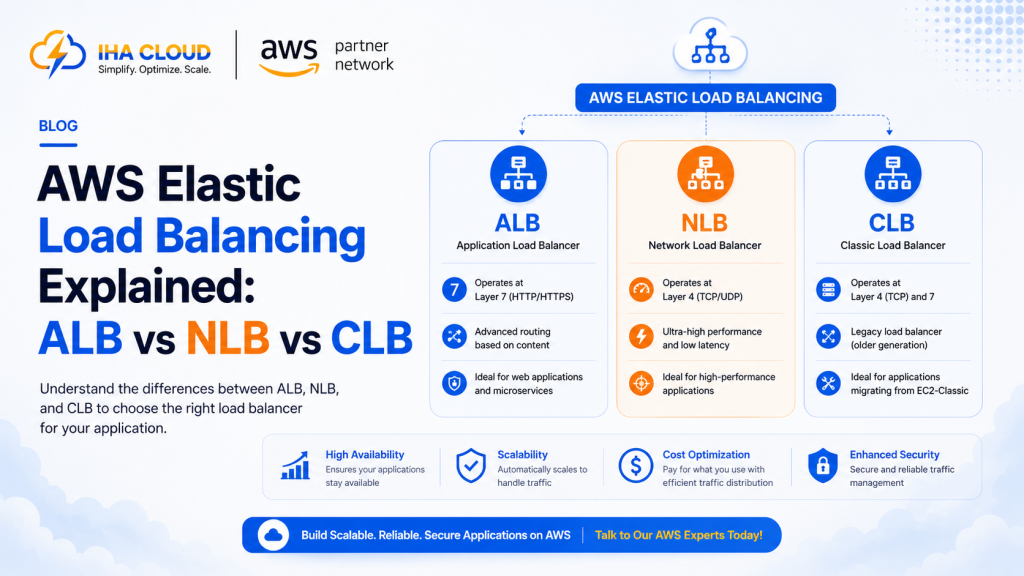
AWS Elastic Load Balancing Explained: ALB vs NLB vs CLB 

A load balancer distributes incoming traffic across multiple servers so no single instance gets overwhelmed, and so a failed instance does not take the whole application down. AWS offers three types, and the right choice depends on what layer of traffic you actually need to manage.  Application Load Balancer (ALB)  Operates at Layer 7 (HTTP/HTTPS), meaning it understands the content of requests, not just the connection.  Network Load Balancer (NLB)  Operates at Layer 4 (TCP/UDP), handling raw network connections without inspecting request content.  Classic Load Balancer (CLB)  The original AWS load balancer, largely superseded by ALB and NLB.  Choosing the Right One  Common Mistakes  For nearly all standard web applications, ALB is the correct default. NLB is a deliberate choice for a specific technical requirement, not a general-purpose upgrade. 

AWS Elastic Load Balancing Explained: ALB vs NLB vs CLB  Read More »

AWS Cost Optimization Checklist 2026

AWS Cost Optimization Checklist for 2026: 15 Ways to Reduce and Control AWS Costs

Your AWS bill rarely becomes expensive because of one bad decision. It usually grows through dozens of small infrastructure decisions that nobody revisits.  An oversized EC2 instance here. An unused EBS volume there. A development environment running 24/7. Data moving unnecessarily between Availability Zones. A Savings Plan based on a usage pattern that no longer exists.  Individually, these costs may look insignificant. Together, they can become a serious drain on your cloud budget.  Effective AWS cost optimization isn’t about making infrastructure as cheap as possible. It’s about getting the right balance of cost, performance, reliability, and business value.  In 2026, that means moving beyond reactive cost-cutting toward a repeatable process built around visibility, prioritization, optimization, measurement, and automation.  For businesses that don’t have the internal resources to continuously audit their AWS environment, working with an AWS cloud partner such as IHA Cloud can help turn cost data into prioritized, actionable improvements.  What Is AWS Cost Optimization in 2026?  AWS cost optimization is the ongoing process of reducing unnecessary cloud spending while maintaining the performance, reliability, security, and scalability a business requires.  The FinOps Foundation’s 2025 State of FinOps report covers organizations collectively responsible for more than $69 billion in cloud spend, highlighting the growing importance of optimization, cost allocation, and forecasting.  The goal isn’t simply to spend less.  It’s to get more business value from every AWS dollar.  The AWS Cost Optimization Framework  Use this five-step loop:  Discover → Prioritize → Optimize → Measure → Repeat  The key insight  The biggest AWS cost isn’t always the most expensive service. It can be the architectural decision that causes multiple services to become expensive.  For example, inefficient application architecture can increase compute, database, storage, and data-transfer costs simultaneously. That’s why effective AWS cost optimization needs to look beyond individual resources.  AWS Cost Optimization Checklist 2026 1. Audit Your AWS Spending  Start with visibility.  Review:  AWS Cost Optimization Hub brings recommendations together across areas such as rightsizing, idle resources, Graviton migration, databases, and Savings Plans.  Example: If EC2 represents 20% of your AWS spend, but data transfer represents 45%, optimizing EC2 first may have limited impact.  Rule: Optimize the largest meaningful cost driver—not simply the easiest one.  If AWS billing data is difficult to interpret, IHA Cloud’s guide on how to read your AWS bill explains where to find key charges and how to use Cost Explorer to analyze spending.  2. Find Idle and Underutilized Resources  Look for:  Before deleting anything, verify its owner, dependencies, retention requirements, and recovery needs.  Use:  Identify → Verify → Remove, Resize, or Schedule → Monitor  3. Right-Size Compute  Review CPU, memory, network, storage performance, and peak utilization—not just averages.  AWS Compute Optimizer can identify potential rightsizing opportunities using historical utilization data.  Use:  Measure → Analyze → Benchmark → Right-size → Validate  For example, an EC2 instance consistently operating well below its allocated capacity may be a candidate for rightsizing, but peak traffic and memory requirements still need to be considered.  4. Evaluate Graviton  AWS reports that Graviton-based EC2 instances can provide up to 40% better price performance than comparable x86-based instances for a wide range of workloads. Actual results vary by workload and configuration.  Consider Graviton when your applications and dependencies support ARM64.  Benchmark first, then migrate workloads where the economics and performance make sense. 5. Review Savings Plans  For predictable compute usage, evaluate:  Don’t commit based on a temporary usage spike. Base commitments on a realistic long-term baseline.  6. Use Spot Strategically  Spot Instances can be useful for interruptible workloads such as:  They aren’t suitable for every production workload. If interruption creates unacceptable operational risk, other capacity options may be more appropriate.  7. Optimize EBS Storage  Review:  Before deleting storage, check:  Owner → Dependency → Retention → Recovery → Cost  8. Match S3 Storage to Access Patterns  Use lifecycle policies to move data through appropriate storage tiers:  Frequently accessed → Infrequently accessed → Archive → Delete  S3 Intelligent-Tiering can automatically move eligible objects between access tiers as access patterns change.  Use case: Application logs may be heavily accessed immediately after creation but rarely used months later. Lifecycle policies can align storage costs with changing usage.  9. Audit Data Transfer  Don’t focus exclusively on compute.  Review:  Ask:  Where does the data originate? → Where does it go? → How much moves? → How often? → Does it cross a billing boundary?  An application can be efficiently right-sized and still have significant costs caused by unnecessary data movement.  10. Right-Size RDS  Review:  A database can have low CPU utilization while still requiring significant memory or IOPS.  Never right-size a production database using CPU alone.  Build Long-Term Cost Controls  11. Make AWS Costs Traceable  Use consistent tags such as:  Environment · Application · Team · Owner · Project · CostCenter  This connects infrastructure spending to specific teams and workloads.  Instead of asking “Why did AWS spending increase?”, you can ask “Which workload caused the increase?”  12. Set Budgets and Detect Anomalies  Set budgets and alerts for accounts, projects, teams, environments, and major services.  Use:  Detect → Investigate → Act  The goal is to identify meaningful spending changes before they become expensive surprises.  13. Automate Repetitive Controls  Automate tasks such as:  Automation turns cost optimization from a recurring manual task into an operational control.  14. Introduce FinOps  AWS cost optimization shouldn’t belong exclusively to engineering.  A mature approach connects:  Engineering + Finance + Operations + Business  Engineering understands infrastructure, Finance understands financial impact, and business teams determine whether the cost is justified by business value.  15. Review Architecture Regularly  Every quarter, ask:  This prevents cost optimization from becoming a one-time cleanup exercise.  A 30-Day AWS Cost Optimization Plan  Week 1 — Visibility: Audit spending, identify major cost drivers, investigate anomalies, and improve tagging.  Week 2 — Quick Wins: Review idle resources, EBS storage, S3 lifecycle policies, and non-production schedules.  Week 3 — Infrastructure: Right-size EC2 and RDS, evaluate Graviton and Spot, and investigate data-transfer costs.  Week 4 — Long-Term Controls: Review Savings Plans, configure budgets, automate recurring actions, and establish regular cost reviews.  The goal isn’t to finish AWS cost optimization in 30 days. It’s to establish a process that continues working afterward.  Common AWS Cost Optimization Mistakes  Optimizing the wrong service: Small savings won’t matter if another service drives most of the bill.  Buying commitments too early: A discount isn’t useful if you’re paying for capacity you don’t consistently need.  Ignoring peak usage: Average utilization doesn’t always represent real capacity requirements.  Ignoring data transfer: Architecture-related data movement can create recurring costs.  Deleting resources blindly: An apparently unused resource may support backups, recovery, or another application.  Measuring cost without performance: A lower bill isn’t a successful optimization if application performance suffers.  How IHA Cloud Can Help With AWS Cost Optimization  Following a checklist can uncover obvious inefficiencies, but deeper optimization often requires analyzing the relationship between billing, infrastructure utilization, application performance, and architecture.  IHA Cloud’s Cost Audit & Optimization service

AWS Cost Optimization Checklist for 2026: 15 Ways to Reduce and Control AWS Costs Read More »

Reserved Instances vs Savings Plans vs Spot Instances

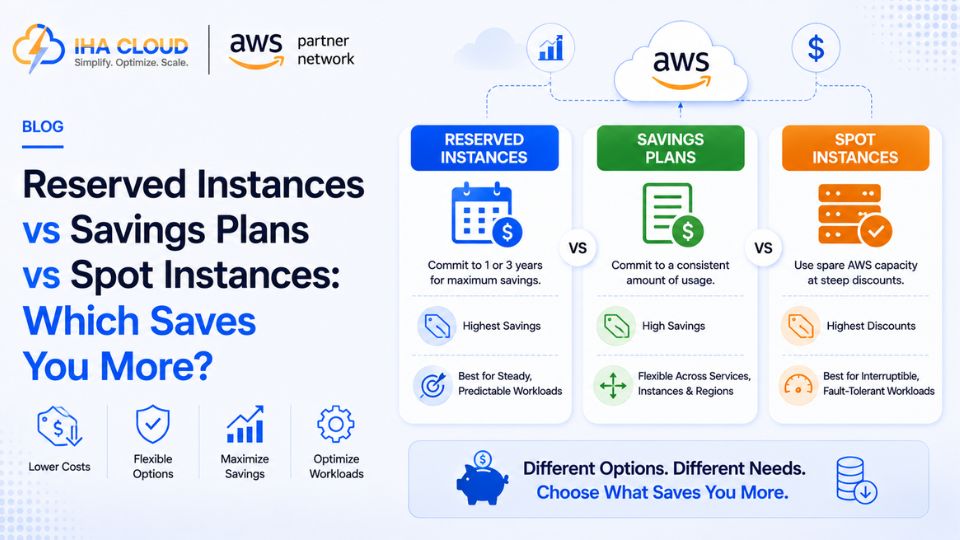
Reserved Instances vs Savings Plans vs Spot Instances: Which Saves You More? 

On-Demand pricing is the most flexible way to run AWS compute, and also the most expensive. Once a workload’s usage pattern becomes predictable, there are three ways to reduce that cost significantly — and choosing the right one depends entirely on how consistent your usage actually is.  Reserved Instances  You commit to a specific instance type, in a specific region, for a 1 or 3-year term, in exchange for a discount of up to 72% off On-Demand pricing.  Savings Plans  A more flexible commitment — you commit to a dollar amount of compute usage per hour, rather than a specific instance type, for a 1 or 3-year term.  Spot Instances  Spare AWS compute capacity offered at discounts of up to 90% off On-Demand pricing, with the tradeoff that AWS can reclaim the instance with a two-minute warning.  Choosing Between Them  A Realistic Approach  Most cost-optimized AWS accounts use a mix of all three: Savings Plans covering the predictable baseline load, Spot Instances handling batch and flexible workloads, and On-Demand covering short-term spikes above the baseline. Reviewing AWS Cost Explorer’s recommendations regularly — rather than committing once and forgetting about it — is what keeps this mix aligned with how the workload actually evolves over time.

Reserved Instances vs Savings Plans vs Spot Instances: Which Saves You More?  Read More »

Migrating WordPress to AWS: A Step-by-Step Guide 

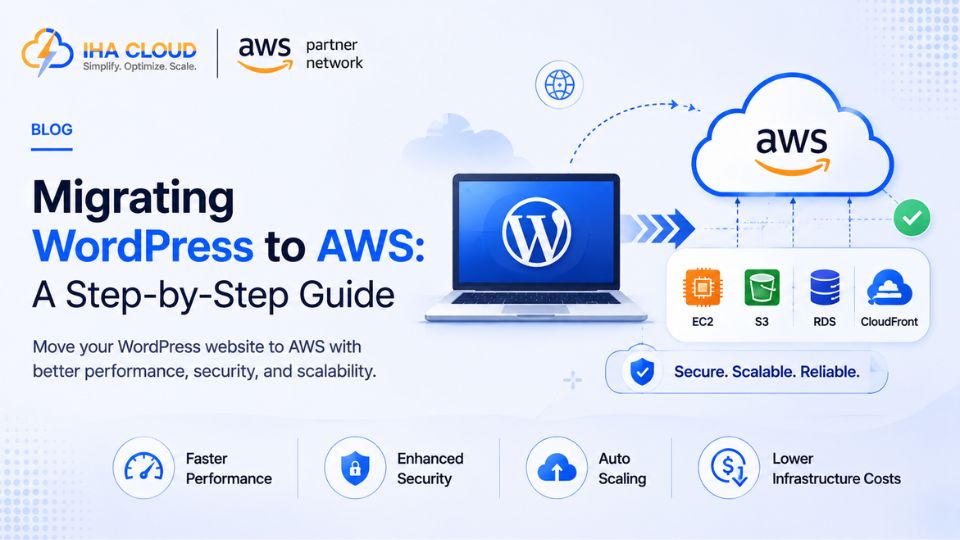
WordPress on shared hosting works fine for a small site, until traffic grows, plugins pile up, and page load times start affecting conversions. Moving to AWS gives you room to scale — but the migration needs to be handled carefully to avoid losing content or breaking the site in the process.  Why Businesses Make This Move  The Basic Architecture  Separating the database onto RDS from day one makes future scaling far easier than keeping it on the same server as the application.  Migration Steps  Reducing Downtime During Cutover  Common Mistakes  After the Move  Once WordPress is running on AWS, set up CloudWatch monitoring, automated RDS backups, and a CDN through CloudFront if it is not already in place. The real value of the migration is not just moving the same site to different infrastructure — it is unlocking the ability to scale each part of the stack independently as the site grows.

Migrating WordPress to AWS: A Step-by-Step Guide  Read More »

Docker and AWS ECS: A Practical Guide to Container Deployment

Docker and AWS ECS: A Practical Guide to Container Deployment 

Most applications start life on a single server. It works fine until deployments get risky, scaling means manually spinning up more servers, and “it works on my machine” becomes a recurring problem. Containers solve this, and on AWS, ECS is the most direct path to running them in production.  What Docker Actually Solves  A Docker container packages your application with everything it needs to run — code, runtime, libraries, configuration — into a single unit. That unit behaves the same on a developer’s laptop, in staging, and in production.  Where ECS Fits In  Amazon ECS (Elastic Container Service) is AWS’s platform for running containers at scale. It handles scheduling, scaling, and health checks so you are not manually managing where each container runs.  For most growing businesses, ECS on Fargate removes an entire layer of operational work — no instance patching, no capacity planning for the cluster itself.  Setting Up a Basic ECS Deployment  Common Mistakes to Avoid  Is It Worth the Migration?  If your team is deploying manually, scaling by adding more identical servers, or fighting environment inconsistencies, moving to Docker and ECS pays for itself quickly in reduced deployment risk and faster releases. For simple, low-traffic applications, it can be more infrastructure than necessary — the right call depends on how much your deployment process is currently costing you in time and incidents. 

Docker and AWS ECS: A Practical Guide to Container Deployment  Read More »